

Adaptive Learning: How It Works and How to Design a Course
What adaptive learning is, what drives it, what the research shows, including Bloom's two sigma, and how to design an adaptive course step by step.

Adaptive learning is instruction that changes what each learner gets next, such as content, order, pace, feedback or assessment, based on evidence about that learner, usually their answers, using rules written by a designer or a model built by software.
- Most adaptive workplace courses can run on rules a designer writes, like skipping a module after two correct pre-check answers, with no AI at all.
- Bloom's two sigma result came from 11 lessons on two school topics, and later reviews put human tutoring nearer 0.4 to 0.8 standard deviations.
- Intelligent tutoring systems lifted scores on tests written for the course by an average 0.73 standard deviations, but by only 0.13 on standardised tests.
- An adaptive course needs a pre-check for each objective and a written rule for who skips, who gets more help and who sees a person.
- Of 104 course requests typed into Coursebox over 90 days, none asked to let learners skip what they already know.
Five questions, about a minute. Answer for one course you would like to adapt to each learner, such as a refresher that experienced and new staff both have to complete. This is a planning aid, not a validated measure or a certification.

Go from storyboard to an interactive course in minutes
Picture the annual good documentation practice refresher at a factory that makes tablets and capsules. A quality control analyst with 20 years at the bench clicks through the 60-minute course in 15 minutes and passes the 10-question quiz at the end. A production operator who started three months ago passes too. A year later, the site's deviation log shows the same four documentation errors it showed the year before. The course gives everyone the same hour, and it cannot tell who already does the job right and who does not.
I'm an instructional designer at Coursebox, where we make AI tools for employee training that turn a brief into a staff course, so I'll mention our product where I tested it. Adaptive learning is meant to solve the problem in that refresher. In this guide I explain what adaptive learning is and what drives it, separate it from personalised learning and learning styles, and set Bloom's two sigma study straight against what the meta-analyses found. I walk through four real cases, then design that refresher as an adaptive course step by step, test it in our product and share two free templates.
What is adaptive learning?
Adaptive learning is instruction that changes what each learner gets next, such as content, order, pace, feedback or assessment, based on evidence about that learner, usually their answers, using rules written by a designer or a model built by software.
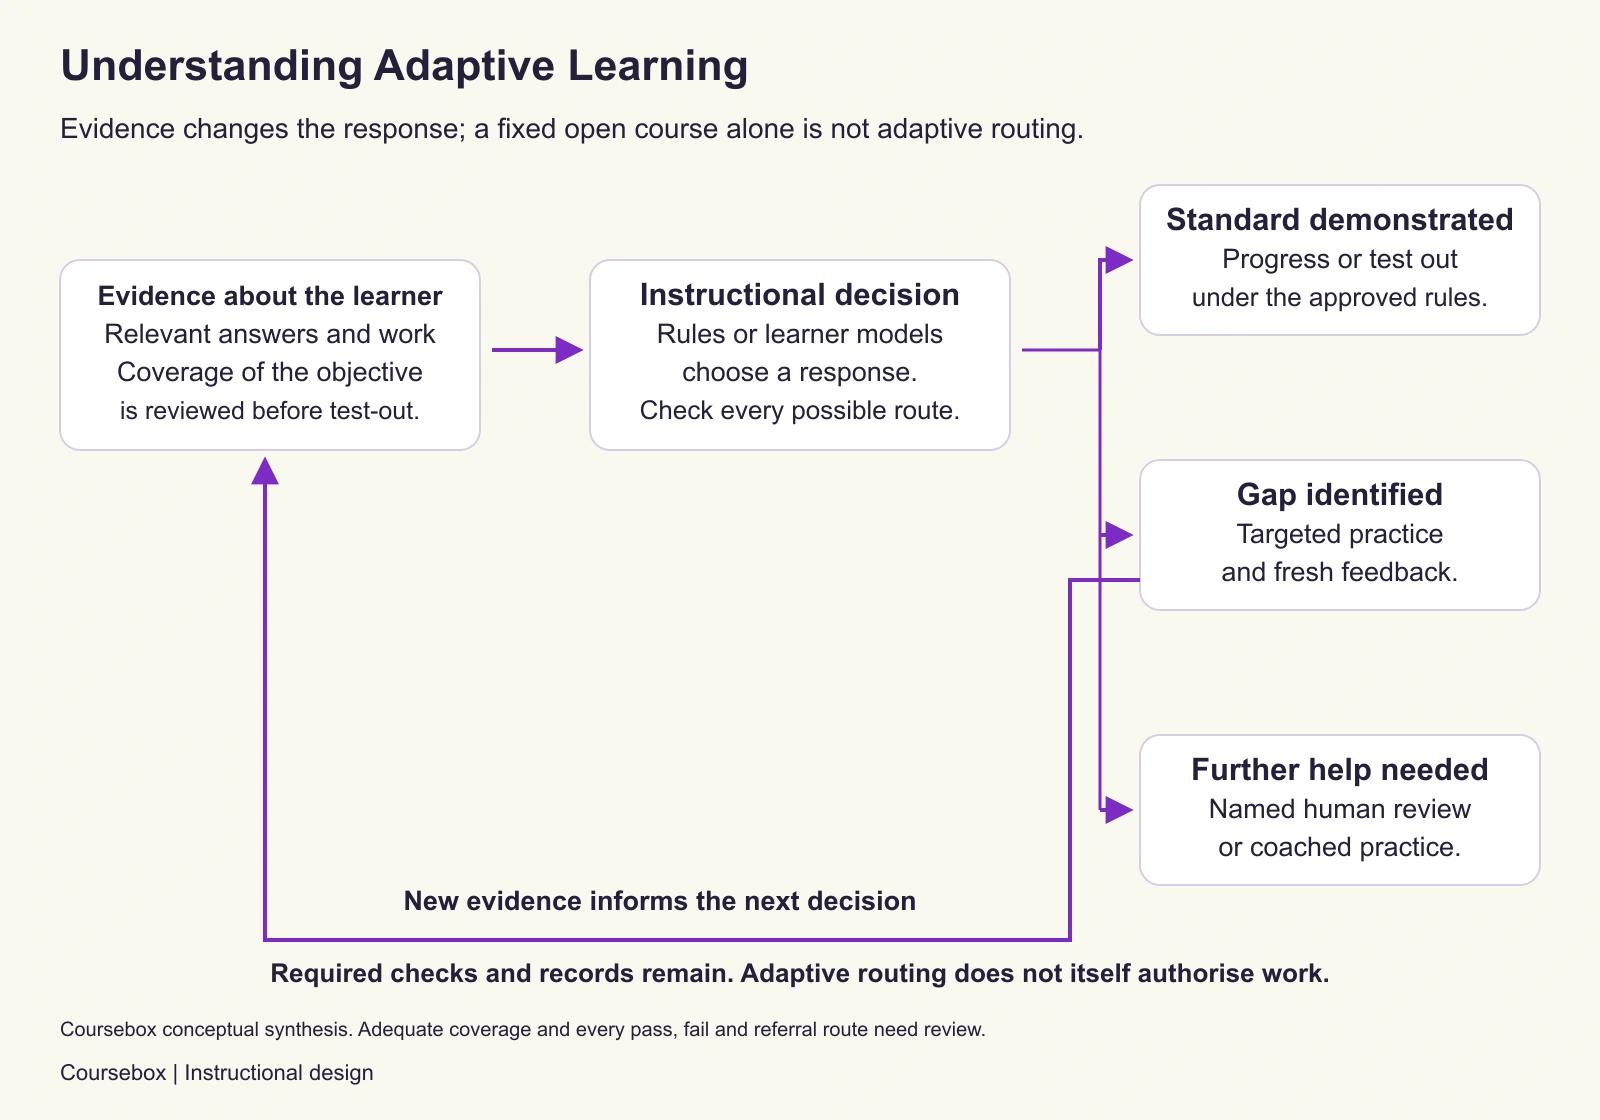
The term has no single originator, and the field has never settled its boundaries. A 2020 paper by Plass and Pawar proposing a taxonomy of adaptivity for learning starts from the problem: "we lack clear definitions of the terms adaptivity and personalization". So it helps to pin down three parts of the definition.
- What adapts. Anything the learner meets next: which module comes up, in what order, how fast, what feedback follows an answer and which questions are asked. The lightest form changes only the feedback on each answer. The heaviest rebuilds the whole route for each person.
- What it adapts to. Evidence about the learner. In practice that mostly means performance: answers to questions, sometimes with a confidence rating or the time taken. Routing people by job role is related, but it responds to a fact about the person, not to what they have shown they can do.
- Who decides. In designed adaptivity, people write the rules in advance. In algorithmic adaptivity, software keeps a running estimate of what each learner knows and picks the next step from it. A 2019 systematic review in BMJ Open by Guillaume Fontaine and colleagues describes the designed kind as "based on the expertise of the educator who specifies how technology will react in a particular situation on the basis of the 'if THIS, then THAT' approach."
The purpose is efficiency as much as effectiveness: people who can already show an objective should not sit through it, and people who cannot should get more than one pass at it. Here is what can adapt, with the question each one asks of a course.
| What adapts | What drives it | The question it asks of your course | What it looks like at work |
|---|---|---|---|
| Feedback | The answer the learner gave | What should a learner see after this wrong answer? | A worked example of the exact error, not "incorrect, try again" |
| Sequence | Scores on a pre-check or a module check | Who can skip this, and who needs more? | An experienced analyst skips a module after two correct pre-check answers |
| Pace and repetition | Right and wrong answers over time | What comes back, and when? | A question answered wrongly returns sooner than one answered correctly |
| Assessment | Earlier answers in the same test | Which question tells you most about this person next? | A placement test that picks harder or easier items as it goes |
| Content by role | A fact about the learner, such as their job | Which content does this role need? | Operators get batch records and analysts get lab records |
In UK schools, "adaptive teaching" is a classroom practice: a teacher adjusts the lesson for the pupils in front of them. Adaptive learning in this guide means the course itself, or the system running it, changes for each learner from evidence about that learner. The two overlap in spirit and differ in who does the adjusting.
Adaptive learning also does not mean AI. The oldest adaptive tools were rules, and a workplace course can adapt on rules alone. A general chatbot does respond to what you type, but unless someone builds a system around it, it keeps no checked record of what you have mastered and no rule for what you should get next.
The lightest form of adaptive learning is feedback written for each answer. A trial with junior doctors in Sydney shows what that buys, and what it does not.

Case study: Junior doctors in Sydney hospitals
This was a randomised crossover trial with interns and residents employed by NSW Health, studying voluntarily. Junior doctors order and read imaging with little radiology training and little time to get more.
- What they did: A University of New South Wales team wrote case-based head CT and chest CT tutorials that gave "Immediate personalised feedback ... after each response". That is designed adaptivity at the level of each answer. The comparison group used links to two reputable radiology websites inside the same platform, so their time could be logged too. After a week the groups swapped topics.
- Evidence and result: Wade and colleagues’ randomised crossover study reported no statistically detected quiz-score difference between adaptive tutorials and web resources (head CT: 86.4% vs 83.5%, p = .33; chest CT comparison: p = .44). Recorded tutorial time was shorter: about 31.5 vs 70.9 minutes for head CT and 21.0 vs 59.8 minutes for chest CT. This was not an equivalence test, so the nonsignificant score differences do not establish equal effectiveness.
- Limitation: The doctors were volunteers, numbers fell from 91 to 50, the outcome was a short quiz rather than how well they read scans on the wards, and the team that built the tutorials ran the study.
- Lesson: These tutorials took less recorded time without a statistically detected quiz-score difference in this study. That supports investigating efficiency for a comparable task, not promising equal learning in half the time for any adaptive course.
How an adaptive learning system works
A useful way to analyse an adaptive system is through three functions: a representation of the subject, evidence about the learner, and rules or models that decide the next instructional response. Systems implement these functions in different ways; they do not all expose three separate software components.
- The domain model: what is to be learned, broken into objectives or skills, with questions that test each one.
- The learner model: the system's current estimate of what this learner can do. In a designed course it can be as plain as "got both pre-check items on objective 2 right".
- The instructional model: the rules or the algorithm that choose the next step from the learner model.
Systems differ mainly in how the learner model is updated and who wrote the instructional model. The table runs from the simplest drivers to the most complex.
| Driver | How it decides | What you need to build it | Example |
|---|---|---|---|
| Fixed rule | If the learner does X, show Y | Questions for each objective and a written rule | Two correct pre-check answers skip a module |
| Mastery threshold | The learner gets more help and new questions until they reach a set score | A pass mark, spare questions and remediation content | Two new questions after a failed module check |
| Spacing rule | Wrong answers come back sooner than right ones | A question bank and a schedule | Wrong returns in 12 days, right in 24, retired after two in a row |
| Adaptive testing | Each question is picked from the answers so far | A large, calibrated question pool | A placement test that stops once it has placed you |
| Knowledge tracing | A probability of mastery per skill, updated after every answer | Many practice items per skill and data to set the model | A tutor that assigns practice until a skill reaches 0.95 |
| Platform learner model | Software combines answers, confidence and time | A vendor platform and content tagged by objective | Refreshers generated for what each person got wrong |
Rules came first. When Sidney Pressey showed his testing machine at the American Psychological Association in December 1924, the learner "must get the correct answer to each question before he can go on to the next", as his 1926 paper put it. Adaptive testing is older still: in a 1982 review in Applied Psychological Measurement, David Weiss calls Alfred Binet's individually given intelligence test "the first adaptive test", because the examiner chose each item from the answers before. Weiss also reported live-testing data in which adaptive tests needed "half the number of items as that of conventional tests to achieve equal levels of reliability".
Knowledge tracing is the classic algorithm, and it is often described wrongly. In Albert Corbett and John Anderson's 1995 paper, each skill is in one of two states, learned or not, and the tutor keeps a probability that it is learned, updated after every answer from four values: the chance it was known at the start, the chance of learning it at each step, the chance of guessing right and the chance of slipping. "That mastery criterion in the tutor is a knowledge probability of 0.95." The model also assumes "There is no forgetting". It estimates the probability that a skill is learned; the chance of learning at each step is only one of its four inputs, not what it reports.
The simplest of these drivers, a spacing rule, is the one with the clearest workplace result.

Case study: Clinicians at eight veterans' hospitals in the United States
This was a randomised controlled trial with primary care clinicians at eight Veterans Affairs medical centres in New England, run in 2010 and 2011. The problem was clinical inertia: medication for patients with high blood pressure often was not stepped up at visits.
- What they did: Clinicians got 32 questions with explanations by email, about one every three days. A fixed rule set the timing: "The adaptive system repeated questions in 12 days if answered incorrectly and 24 days if answered correctly", and a question answered correctly twice in a row was retired. A leaderboard added competition. The control group got the same content as an online posting with email reminders. This is designed adaptivity.
- Evidence and result: In Kerfoot and colleagues' 2014 trial in Circulation: Cardiovascular Quality and Outcomes, 111 clinicians enrolled and 104 sat the post-test. The game group scored 90% against 78% (Cohen's d 0.8). Across 14,336 patients, those of the game clinicians reached their blood pressure target slightly sooner, 142 against 148 days at the median after adjustment (hazard ratio 1.043, 95% CI 1.007 to 1.081). Before adjustment the difference was not significant.
- Limitation: Only 37% of eligible clinicians enrolled, the game group also received more emails, and the rule came bundled with game mechanics, so adaptivity alone cannot take the credit. The lead author created spaced education and disclosed equity in a company built on it, although its platform was not used.
- Lesson: A plain rule (bring back what someone got wrong sooner, retire what they get right twice) is adaptive learning, and it needs no AI. Expect the knowledge gain to be much larger than the change in practice, and measure practice if you can.
Designed or algorithmic: the first decision to make
Before choosing any tool, decide who will write the logic. With designed adaptivity, you write every rule and can explain every route. With algorithmic adaptivity, a vendor's model makes the choices from data, and you supply content tagged by objective.
| Question | Designed (rule-based) | Algorithmic (learner model) |
|---|---|---|
| Best for | Procedures, compliance and safety training where every route must be explained | Large learner numbers working through a big, stable bank of items |
| Weak spot | Routes only on what your questions measure; every branch is content someone writes and keeps current | Harder to explain to an auditor; needs many items and plenty of learner data |
| What you need | Two or more questions per objective, written rules, pass marks and locks, or an administrator | A platform, content tagged by objective and skill, and time to tune it |
| Use it when | Objectives are clear and the group is small to medium | The same content will serve many learners for years |
Educator-designed rules can operate without a historical learner dataset, but still use current answers or other relevant learner evidence. Validate the items, the decision rules and every route. Statistical learner models and fixed rules can also coexist in one system.

Case study: Newborn care providers in Mwanza, Tanzania
This was a single-group implementation study at one zonal hospital and three health centres, run in 2022 and 2023. Multi-day in-service courses on newborn care are hard to sustain, do not respond to what each provider already knows, and what people learn fades.
- What they did: Doctors, nurses, clinical officers and other staff studied nine modules built from national guidelines on their own phones, for professional development credit. The platform scored every answer for correctness and confidence, built a model of each learner, set the pace and order, and generated refreshers, and a module ended only at "100% conscious competence". People sat around it: a programme manager, reminders by email after 2 days, by WhatsApp after 5 and a meeting after 30, and a data allowance of about US$4 a month. This is algorithmic adaptivity.
- Evidence and result: In Meaney and colleagues' 2024 paper in BMJ Open, 195 providers enrolled and 110 finished the initial modules. Among those 110, the share of answers that were both correct and confident rose by an average of 42 percentage points. Refreshers were another story: average progress on them was 7%, nobody finished them all, and the main reasons given for going inactive were "no time" (69%) and "forgot to use" (50%).
- Limitation: There was no control group, the gain was measured inside the platform and only among people who finished, which flatters the average enrolee, and confidence was self-rated. Two co-authors were paid by the platform's vendor.
- Lesson: In this study the algorithm exposed answers people were confident about but got wrong. It did not get busy staff to come back: finishing came with a programme manager and a ladder of reminders, and even then the spaced refreshers were almost ignored. Budget for protected time and follow-up.
Adaptive vs personalised vs differentiated learning
The three terms are used as if they meant the same thing, and they do not. The useful difference is who decides, and on what evidence.
| Approach | Who decides | On what evidence | Example at work |
|---|---|---|---|
| Adaptive learning | The course, through a designer's rules or a software model | The learner's answers and performance | A pre-check decides which modules an operator takes |
| Personalised learning | Varies, because the term has no shared definition | Each learner's needs, goals and interests | A development plan built around one person's career goal |
| Differentiated instruction | The teacher or trainer | Readiness and interest, read in the room | A trainer gives a faster table harder cases in a workshop |
| Learner control | The learner | Their own choice | A learner picks which module to open first |
Carol Ann Tomlinson's ERIC digest on differentiation puts it plainly: "At its most basic level, differentiation consists of the efforts of teachers to respond to variance among learners in the classroom." Personalised learning is looser. A 2017 RAND report on schools adopting it notes that "there is not yet a widely shared definition of PL", and across 32 schools and about 5,500 students it estimated effects of about 0.09 standard deviations in maths and 0.07 in reading, against matched comparison students rather than a randomised group, with only the maths result statistically significant.
Learner control is the usual fallback when a course cannot route: the learner picks. A 2014 meta-analysis of learner control by Karich and colleagues found that the overall effect of giving learners control within educational technology "was almost zero (g = 0.05)". Letting people choose is not, on its own, adaptive learning.
A system can change content according to a reported style, but that does not establish a learning benefit. Use relevant performance evidence and instructional needs to choose a route. The matching hypothesis lacks adequate evidence; preference is not proof of the method someone needs.
That conclusion comes from Harold Pashler and colleagues' 2008 paper in Psychological Science in the Public Interest. The authors are careful to say that many versions of learning styles have never been tested at all, and until one is, it has no place in a design. The learner variable with real evidence behind it is prior knowledge.
Where adaptive learning came from
The idea is about a century old, and most of its history is rules, not algorithms.
- Binet's test, early 1900s. The examiner picked each question from the child's earlier answers and stopped when the result was clear, which is why Weiss calls it the first adaptive test.
- Pressey's machine, 1924 to 1926. Sidney Pressey's device held each question until the learner answered it correctly. He described it in 1926 as an apparatus that "gives tests and scores, and teaches".
- Skinner's teaching machines, 1958. B. F. Skinner's paper in Science credited Pressey ("Such machines, Pressey (1926) pointed out, could not only test and score, they could teach") and argued that machine instruction "would permit each student to proceed at his own rate."
- Bloom's mastery learning, 1968. Benjamin Bloom took John Carroll's view of aptitude as "the amount of time required by the learner to attain mastery" and built a classroom method on it: teach, check, correct, check again. His paper Learning for Mastery stated a belief, not a finding, that "Most students (perhaps over 90 percent) can master what we have to teach them".
- Bloom's two sigma problem, 1984. Bloom challenged researchers to find methods of group instruction as effective as one-to-one tutoring, the subtitle of his paper.
- Intelligent tutoring systems, 1980s to 1990s. Tutors that modelled each learner's skills, with knowledge tracing as the classic method.
- AI-enabled systems, 2010s onward. A 2024 meta-analysis by Wang and colleagues of 45 studies of AI-enabled adaptive learning systems reported a pooled effect of g = 0.70 against non-adaptive teaching. I read the abstract only, and one line from it deserves more attention than the headline: "The type of AI used in the adaptive engine did not moderate the effects."
Bloom's two sigma problem, told accurately
Benjamin Bloom's 1984 paper in Educational Researcher, The 2 Sigma Problem, is one of the most quoted claims in adaptive learning. It is usually told as "one-to-one tutoring raises achievement by two standard deviations", and most of that sentence needs qualifying.
What the studies were. Bloom summarised two University of Chicago doctoral studies, by Anania and by Burke. Students in grades 4, 5 and 8 were randomly assigned to learn probability or cartography in one of three ways: a conventional class of about 30, the same class with mastery learning (formative tests, corrective work and a parallel retest), or tutoring with the same feedback and retesting. "In each sub-study, the instructional treatment was limited to 11 periods of instruction over a 3-week block of time" (p. 4). Bloom gives no sample sizes.
What it found. "The average student under tutoring was about two standard deviations above the average of the control class (the average tutored student was above 98% of the students in the control class)" (p. 4). Mastery learning came out about one standard deviation above the conventional class.
What gets lost in the retelling.
- The 98% is a percentile, not a mastery rate. It places the average tutored student against the control class. It does not mean 98% of tutored students mastered the topic.
- "Tutoring" was not always one to one. Bloom's own definition was "a good tutor for each student (or for two or three students simultaneously)". Kurt VanLehn's 2011 review in Educational Psychologist points out that five of the six experiments had each tutor working with three students.
- The tutored students also got the mastery loop. They had the same feedback, corrective work and retests as the mastery learning group.
- The famous curve is a drawing. Paul von Hippel's 2024 analysis in Education Next notes that Bloom's figure "wasn't fit to actual data", and Bloom himself notes that the mastery learning and tutoring distributions were "highly skewed".
Von Hippel's reading of the original studies separates the two ingredients.
That leaves about 0.9 for tutoring itself, on narrow end-of-unit tests of unfamiliar topics. Later syntheses are lower still. VanLehn found an average effect of d = 0.79 for human tutoring across 10 comparisons. In a 2016 review, James Kulik and J. D. Fletcher put the median effect of human tutoring across five meta-analyses at 0.40, "far from Bloom's (1984) two-sigma effect". Von Hippel's conclusion is that the two sigma claim is "exaggerated and oversimplified", and that "About one-third of a standard deviation seems to be the typical effect of an intense, well-designed program evaluated against broad tests."
For a course designer, the useful half of Bloom's paper is the half you can build: teach, check each objective, correct what was wrong and check again with new questions. Even that is not a guaranteed sigma. Robert Slavin's 1987 review of group-based mastery learning in schools found a median effect of +.04 on standardised tests across 7 studies and +.255 on experimenter-made tests across 8. The gains show up on tests of the material taught and are close to zero on broad measures.
Does adaptive learning work? What the research shows
Mostly yes on the material taught, and much less on broad tests. Adaptive tutoring beats one-size-fits-all classes on well-defined tasks and roughly matches a human tutor, but the effect shrinks on standardised tests, in large samples and over long deployments. The best evidence comes from intelligent tutoring systems, the most studied kind of adaptive learning. Each row in this table is a synthesis, not a single study.
| Comparison | Evidence base | Effect | What limits it |
|---|---|---|---|
| Tutoring systems vs conventional classes | 50 evaluations (Kulik and Fletcher, 2016) | Median 0.66 SD; random-effects g 0.50 | Test type, sample size and subject are entangled |
| Same, studies with up to 80 people vs over 250 | 26 and 13 studies | 0.78 vs 0.30 | Large studies show smaller effects |
| Tutoring systems vs large-group teaching | 66 comparisons (Ma and colleagues, 2014) | g 0.44 | Classroom comparisons; results varied widely overall |
| Tutoring systems vs one-to-one human tutoring | 5 comparisons (Ma and colleagues, 2014) | g -0.11, not significant | Few studies |
| Tutoring systems in school maths | 26 reports, 34 samples (Steenbergen-Hu and Cooper, 2013) | g 0.09, not significant | Smaller over a full school year |
| Adaptive e-learning, health professionals' knowledge | 13 studies pooled (Fontaine and colleagues, 2019) | SMD 0.70, not significant | Very low quality evidence; high risk of bias |
| Adaptive e-learning, health professionals' skills | Same review | SMD 1.19 | Low quality evidence |
Kulik and Fletcher's 2016 meta-analysis in Review of Educational Research is the main source for the first two rows: "The median effect of intelligent tutoring in the 50 evaluations was to raise test scores 0.66 standard deviations over conventional levels, or from the 50th to the 75th percentile." The detail that changes what you should promise is how the effect depends on the test.
The authors warn that test type is tangled up with sample size, subject and grade, so it is not a clean cause. Not every review finds the gap either: Ma and colleagues' 2014 meta-analysis found almost none under a random-effects model. But a course quiz written by the same people who wrote the course is the easiest test to pass, and an adaptive course that drills to its own quiz can look better than it is.
The Ma and colleagues meta-analysis found a positive average effect against teacher-led large-group instruction. In five comparisons with individual human tutoring, it did not detect a statistically significant difference (g = -0.11, 95% CI -0.31 to 0.10). That interval includes meaningful differences, so it does not prove equivalence to a human tutor.
Nearly all the rigorous workforce evidence I found comes from health care and defence, and the developers ran most of the evaluations. For a workplace team, the defensible promises are less time for people who already know the material and a check on every objective for everyone, not a fixed gain in scores.
The worked example: a good documentation practice refresher
Here is the hypothetical example I'll design from here on. An Australian contract manufacturer makes tablets and capsules at one site, with about 180 production operators and quality control (QC) analysts. Operators fill in batch records, line clearance checks and weighing records. Analysts keep lab notebooks and chromatography data. Experience ranges from 3 months to 25 years, and everyone must complete the good documentation practice (GDP) refresher every year. Years of service do not show who documents correctly: individual work samples and relevant entry checks provide better evidence than years of service.
The problem is last year's course. Everyone took the same 60-minute course with a 10-question quiz at the end. Experienced staff clicked through in 15 minutes and passed. New starters passed too. The following year the deviation log showed the same four documentation errors.
The course uses only the site's procedure, SOP GDP-001 Good Documentation Practice:
SOP GDP-001 and its rules are invented for this example. They make the practice decisions judgeable; an actual manufacturer must use its approved documentation procedure. The two-item routing rule is illustrative, not a universal minimum or a validated mastery threshold.
- Record each entry at the time of the activity.
- Correct an error with a single line through it so the original stays readable, then write the correct value, your initials, the date and the reason. No correction fluid and no overwriting.
- Record a missed entry as a late entry: today's date and time, the words "late entry", the reason and a supervisor's countersignature. Never backdate.
- Never sign for something you did not do or see. Report any pressure to do so, any pre-filled record or any shared login to your supervisor or QA the same day.
Training records must show, for each person, which objectives they tested out of and which modules they completed. So the refresher has four objectives, one short module each of about 8 minutes: record at the time of the activity, correct an error properly, handle a missed entry as a late entry, and recognise and report a data integrity concern. Operators also need a module on batch records and line clearance, and analysts one on lab records and audit trails.
The intended outcome is that each person spends time only on the objectives they cannot yet show, and the site can show an auditor who was checked on what. The course cannot prove that documentation errors fall; that needs next year's deviation log.
The example suits adaptive learning because it needs every move a workplace team can build without an algorithm: a diagnostic by objective, a test-out rule, routing by role, a mastery check, remediation, a person when the rules run out, and a record. It also shows the limit: rules can only route on what the questions measure.
How to create an adaptive course, step by step
No single model owns this process, so the steps are my synthesis of mastery learning, the rule-based drivers of adaptivity and the cases in this guide. Each step is carried through the GDP refresher.
- Decide whether adaptivity is worth building. It pays when learners differ widely in what they already know, everyone has to complete the course, you can check each objective with questions, and the content will stay stable long enough to repay the extra writing. It rarely pays for a small group with similar experience, content that changes every month, or objectives no question can check. The GDP refresher passes on all four counts: experience runs from 3 months to 25 years, everyone must complete it every year, each SOP rule can be tested with a scenario, and SOP GDP-001 is stable.
- Write objectives you can route on. Each objective needs one observable decision you can test with a scenario, such as "correct an error properly". Objectives like "understand GDP" cannot route anyone. If you use Bloom's taxonomy to write them, classify the thinking each decision needs, not the verb.
- Write a pre-check with at least two items per objective. Use short scenarios built from real record excerpts, so an item tests the decision and not the wording of the SOP. The GDP pre-check has eight items, two per objective, such as these four:
- Objective 1: An operator weighs the binder at 10:05 and writes it in the batch record at 11:30, after the break, as 10:05. Correct answer: not acceptable; record at the time, or make a late entry with the actual entry date and time, the reason and the supervisor countersignature required by this fictional SOP.
- Objective 2: 25.4 kg was written as 24.5 kg. Correct answer: a single line through 24.5 so it stays readable, then 25.4, initials, date and the reason "transcription error".
- Objective 3: Yesterday's line clearance check was done but not signed. Correct answer: sign today as a late entry with the reason and a supervisor's countersignature; never date it yesterday.
- Objective 4: A colleague asks you to sign as second checker for a weighing you did not see, because "it's just a formality". Correct answer: refuse, and tell your supervisor or QA the same day.
- Write the routing rule, and decide who applies it. For the refresher: both pre-check items on an objective right means that module is skipped and recorded as tested out; one or none right means the learner takes it. Two items guard against guessing. A learner guessing on a four-option question is right one time in four, and on two such questions one time in 16. Then decide who sends people down each route: the platform, an administrator who enrols people by their result, or the learner, who is told what their result means.
- Add a mastery check, remediation and a person. Each GDP module ends with two new items, and both right means the learner moves on. If not, they get a remediation page with a worked example of that exact error and the SOP clause, then two more new items. A second failure flags them for a 15-minute coached session with the QA trainer, outside the course. Remediation has to be different from the module, not the same page again, and the coached session is the step where a person takes over from the rules, much like the graduated help described in the zone of proximal development.
- Route by role where the job decides the content. Operators get "Batch records and line clearance", built on a pre-filled line clearance checklist. QC analysts get "Lab records and audit trails", built on a chromatography result reprocessed with no recorded reason. This routing uses a fact about the learner, not a score, so it is the easiest to set up through enrolment.
- Everyone sits four fresh scenario items, one per objective, with each critical response required in this fictional course. A final check reduces reliance on a pre-check result but cannot guarantee that lucky answers or unmeasured gaps are caught. The QA trainer must judge whether the items adequately sample the required decisions before any test-out rule is used. Course completion does not authorise work outside the site’s approved procedures.
- Keep a record an auditor can read. For each person: the objectives they tested out of, the modules they completed, the final check result and any coaching referral. The QA trainer reviews the referrals.
- After launch, sample actual documentation work for procedure use as Level 3 behaviour evidence. Track deviation rates separately as organisational results, accounting for production volume, audit intensity and other process changes. A raw error count does not isolate a training effect.
Step 3 is where front-loaded tailoring is cheapest to build, and a Dutch trial shows its limit. Practice nurses in Dutch general practices were following the national nine-step guideline for counselling smokers less well than intended. In de Ruijter and colleagues' 2018 trial in the Journal of Medical Internet Research, they got e-learning modules and a feedback letter tailored once to their answers on a baseline questionnaire. Of 269 nurses who completed the baseline, 211 were analysed, and the programme had no overall effect on their self-reported adherence to the nine-step guideline (P = .19). Only nurses with above-average counselling experience improved, by about 0.6 of a step, and nurses visited the modules only three times on average. The limits: adherence was already high at the start (8.5 of 9 steps), the outcome was self-reported, and the developers ran the trial. The lesson for the refresher: a diagnostic only helps if people then work through what it sends them to, and if they can act on it.
There is a second reason for step 4 beyond saving time. Help that a new starter needs, such as a fully worked example, can get in the way of an expert. The researchers who named the expertise reversal effect wrote that "Instructional techniques that are highly effective with inexperienced learners can lose their effectiveness and even have negative consequences when used with more experienced learners." Our guide to cognitive load theory covers the effect in detail. A test-out rule protects the 25-year analyst from material written for someone in their first month.
The adaptive design plan for the GDP refresher
Here is the plan for the four objectives, with the same rules on every row.
| Objective | Pre-check | Both right | One or none right | Module check failed | Failed again |
|---|---|---|---|---|---|
| 1. Record at the time of the activity | 2 scenario items, including the binder weighed at 10:05 | Skip Module 1; recorded as tested out | Take Module 1 | Worked example of a delayed entry, SOP clause 1, then 2 new items | 15-minute coached session with the QA trainer |
| 2. Correct an error properly | 2 scenario items, including 25.4 kg written as 24.5 kg | Skip Module 2; recorded as tested out | Take Module 2 | Worked example of a single-line correction, SOP clause 2, then 2 new items | 15-minute coached session with the QA trainer |
| 3. Handle a missed entry as a late entry | 2 scenario items, including the unsigned line clearance | Skip Module 3; recorded as tested out | Take Module 3 | Worked example of a late entry, SOP clause 3, then 2 new items | 15-minute coached session with the QA trainer |
| 4. Recognise and report a data integrity concern | 2 scenario items, including the request to sign as second checker | Skip Module 4; recorded as tested out | Take Module 4 | Worked example of refusing and reporting, SOP clause 4, then 2 new items | 15-minute coached session with the QA trainer |
On top of these rows, every operator takes the batch records module and every analyst the lab records module, and everyone sits the four-item final check. The module checks are formative and the final check is summative; our guide to formative vs summative assessment explains why the two need different questions.
Plan an adaptive course one objective at a time: the pre-check items, the test-out rule, the module, the mastery check, the remediation, when a person steps in and what the record shows, plus who applies each route. Filled in for the good documentation practice refresher, with blank pages for your own course. Editable Word file, no email required.
For every rule, name who applies it before you build. A rule nobody is assigned to apply turns into advice on a page, and the record of who tested out never gets made.
What Coursebox course requests say about adaptive learning
To see whether people brief adaptive courses, I looked at course requests typed into Coursebox in the 90 days to 7 October 2026: one per person, from English-language browsers, with no uploaded file. Of 266 prompts, 104 were course requests. I had two independent AI readers classify all 104 against written definitions, then re-read every positive call in full myself. Counts use the union of the two readers’ classifications after my review. Treat them as classification estimates, not statistical classification estimates, with possible missed and borderline cases.
None of the 104 asked to let learners skip what they already know, and none asked for a learner's answers to change what they saw next. At most 5 asked for anything adaptive at all, and only one of those was for work: a warehouse and workshop safety induction with a final test that had to be passed before starting the job, which is a gate at the end, not a route.
At most 27 of the 104 were for workplace training. Five of those 27 described learners in different roles or with different experience, such as security guards with their supervisors, or new HR staff alongside trainers, supervisors and managers. All five asked for one course for everyone.
The sample is small, it covers what people typed rather than finished courses, and trainers may route learners outside the builder, by enrolling different groups in different courses. In this sample, a mixed group of learners did not lead anyone to ask for more than one route, so if you want an adaptive course, write the pre-check, the routing rule, what happens after a wrong answer and the record into the brief yourself.
Benefits of adaptive learning
Adaptive designs can offer the following benefits. The evidence and the conditions differ for each.
- Less time on material already mastered. A design that permits learners to skip content after demonstrating the relevant knowledge can reduce unnecessary study. Check the time spent on the diagnostic as well as any content skipped.
- Higher scores on well-defined tasks. Kulik and Fletcher's 2016 meta-analysis put the median effect of intelligent tutoring at 0.66 standard deviations over conventional teaching, mostly on course tests rather than broad ones.
- Help that fits the learner. A fully worked example helps a new starter and can get in the way of an expert, which is the expertise reversal effect. Routing can provide different support, provided the diagnostic and the available versions fit the skill being taught.
- Visible gaps by objective. When the design checks each required objective and supplies useful feedback, the trainer can inspect individual gaps instead of relying on a course average. Not every adaptive system implements this.
Disadvantages and limits of adaptive learning
Adaptive learning has real costs, and its evidence is narrower than its marketing.
- The evidence is strongest on well-defined tasks. VanLehn's review covered STEM tasks with right and wrong answers and excluded reading, second languages, music and sports. Workplace judgement calls are further from that evidence base.
- Effects shrink at scale and on broad tests. Large studies and standardised tests show much smaller effects than small studies and course quizzes, so plan for the smaller number.
- Weaker learners do not always gain. In school maths, Steenbergen-Hu and Cooper found a negative effect for low achievers in the three studies that reported them separately.
- Self-paced mastery can cut completion. A 1990 meta-analysis of mastery learning by Chen-Lin Kulik and colleagues found positive effects on exams across 108 evaluations, but also that "self-paced mastery programs often reduce the completion rates in college classes." I read the abstract only.
- Slower learners pay in time. Bloom saw this in 1968: "Whether mastery learning is worth this great effort for the students who may take several years is highly questionable." In a workplace course the cost is smaller, but remediation and coaching still take hours someone has to fund.
- People do not always come back. Rules and algorithms decide what comes next, but they cannot make anyone open it, as the Tanzanian and Dutch cases showed.
- Authoring and upkeep grow with every branch. I have no peer-reviewed figure for the cost, so here is the plain version: every route is content someone writes, checks and keeps current when the SOP changes. Two items per objective in the pre-check, two in each module check, two more after remediation and four in the final check come to 28 scenario items for the four GDP objectives, before the role modules.
- Rules can only route on what the items measure. A learner who gets two scenario items right may still backdate a record when the line is busy. The final check, the record and the deviation log are there because the pre-check is not the job.
- Algorithms are hard to explain. Wayne Holmes and colleagues' 2022 framework for ethics of AI in education calls for attention to "fairness, accountability, transparency, bias, autonomy, agency, and inclusion". In a regulated workplace, ask whether you could explain to an auditor why one person was routed past a module and another was not.
Using adaptive learning with an AI course builder
On 12 October 2026 I briefed Coursebox to build the GDP refresher. Coursebox is our product, so weigh my account with that in mind. The brief gave the four SOP rules word for word, the four objectives, the four example pre-check items with their answers, the routing rule, the module checks, remediation and coached session, the two role modules, a final check for everyone, and a wrap-up as the very last section. It said: "Make the course actually send each learner to the right modules; do not just tell them which to read."
The first outline was too thin: 3 sections, 3 pages and one quiz, with the routing only in a page title. One follow-up message asked for the sections in the briefed order, and asked the builder to make the routing real or say plainly that it could not. That fixed the order, and the builder answered the routing question directly. The second outline had 10 sections in the order I asked for. In the generated course the pre-check was a quiz with an 80% pass mark, each objective had a module page, a knowledge check and a remediation page, the Module 1 remediation page kept the coached-session escalation, and the two role modules and a final check followed. The builder was also honest about its limit: "The outline defines the test-out and remediation rules, but I cannot create score-based or role-based automatic routing from this structure step alone; that routing must be configured in the course editor or LMS."
The one issue showed up in learner view. Every learner's menu listed all four modules, all four remediation pages and both role modules. With the default settings each section was "Locked", so the Next button stayed disabled until the current activity was complete, and clicking ahead to Module 2 in the menu did nothing. The locks hold each learner on a section until they finish it, the intended gate depended on an overall 80% mark, which did not establish per-objective mastery. It also meant a 25-year analyst who aced the pre-check still had to go through every module, every remediation page and both role modules. In the course editor, the controls I found were a "Locked" or open navigation toggle for each section, a visibility setting for each block ("Visible to everyone", "Hidden from everyone" or "Hidden from learners") and a course-level "Manage prerequisites" option for course-to-course order. I found no score- or role-based routing in those controls during this test.
So I tried the workaround our support team had described, and checked it in the product. I switched the four objective module sections to open navigation in the section menu, checked that Module 1 showed open navigation, switched to learner view and clicked from the Module 1 area straight to Module 2's first page, "Correct Without Obscuring". It opened. Before the change, the same click did nothing.
Opening navigation through the course gave learner control over order. That setting alone did not implement performance-based adaptivity: it did not select objective modules from the pre-check result. The proposed workaround needs a reviewed objective-by-objective result, explicit route instructions, a named person to apply and record the route, and the required final checks. It remains a proposal, not a tested routing feature in this course.
I checked the outline, the editor settings and learner view with my own account. I did not complete the quizzes as two separate test learners, so I have not watched the gate hold a failing learner after the change, and I did not test prerequisites or pathways or check what the learner report records. Two smaller fixes are still needed before use: the generated pre-check had 4 questions rather than the 8 I briefed, and the Module 1 remediation page changed a briefed fact, describing the operator as recording the weighing "as 11:30 AM" when the error in the brief was writing 10:05 at 11:30. The navigation change let my account move between sections. It did not establish a reviewed per-objective result, enforce a test-out rule or verify the learner record. Those remain implementation checks.
Before using this course, replace or revise the four-item pre-check so it supports the intended per-objective decisions, correct the overall 80% rule, and test every pass, fail, repeat and referral route. An open-navigation course and a completion percentage do not establish the routing or mastery checks in the brief. No new product test is claimed here.
An item bank with room for two scenario items per objective, the correct answer and what a wrong answer tells you, plus a routing table for every result (test out, take the module, remediation, a coached session, the final check, routing by role) and a checklist to test the rules before you build. Partly filled in for the good documentation practice refresher, with blank pages. Editable Word file, no email required.
Putting adaptive learning to work
Adaptive learning is a course that changes what each person gets next from evidence about them. For most workplace training that evidence is a short set of scenario questions per objective, and the logic is a handful of rules you can write down and explain. The research supports it as a way to save time for people who already know the material, with gains on what was taught rather than on broad measures. It does not support promises of two sigma.
So treat adaptivity as a design job before it is a software purchase. Write the objectives, the items, the rules, the help that comes after a failed check and the record, and then decide who applies each route.
Your next step: take one compulsory refresher your staff repeat every year, write two scenario items for each of its objectives, and try them on three experienced people and three new starters before you build anything.
Frequently Asked Questions
Adaptive learning is instruction that changes what each learner gets next, such as content, order, pace, feedback or assessment, based on evidence about that learner, usually their answers, using rules written by a designer or a model built by software. The rules can be as simple as letting someone skip a module after a pre-check, or as complex as a tutoring system that estimates mastery of each skill.
A rule-based example is a question bank that brings a question back after 12 days if it was answered wrongly and after 24 days if it was answered correctly, and retires it after two correct answers in a row, as in a 2014 trial with US clinicians. An algorithmic example is a tutoring system that keeps a probability of mastery for each skill and assigns practice until that probability reaches 0.95. In workplace training, a familiar example is a pre-check that lets people skip modules they can already show.
Adaptive learning systems are usually described in three parts: a domain model that breaks the content into objectives or skills with questions for each, a learner model that estimates what each learner can do, and an instructional model of rules or algorithms that chooses the next step. A rule-based course has all three, even if the learner model is only a record of pre-check results.
Adaptive courses take more writing and upkeep, because every route needs its own content and questions. The evidence is strongest on well-defined tasks and shrinks on broad tests and in large deployments. Algorithms can be hard to explain to learners and auditors, self-paced mastery can reduce completion, and no system makes people come back for refreshers they do not have time for.
Adaptive learning means the course or system changes what a learner gets next from evidence about that learner, usually their answers. Personalised learning has no shared definition; it usually means tailoring learning to each person's needs, goals and interests, often across a whole programme and often with the learner or a teacher deciding. Adaptive learning is one way to personalise, but personalisation does not have to be adaptive.
Carolina Martin
Carolina is a highly experienced learning designer with tech start-up experience. She is based in Sydney and previously designed courses alongside Coursebox founder Travis in a previous job. She is passionate about delivering engaging learning experiences and brings the same perspective to customer experience too. She manages our customer support documentation and product testing processes.

